|
I am a Ph.D. student (2020-2026) at the State Key Lab of CAD&CG, Zhejiang University, advised by Prof. Guofeng Zhang and Prof. Zhaopeng Cui. During my Ph.D., I work closely with Yinda Zhang. I used to visit Computer Vision and Geometry Group at ETH Zürich, advised by Marc Pollefeys. My research interests are in multimodal model, video generation, world model and 3D computer vision. |
|
|
|
|
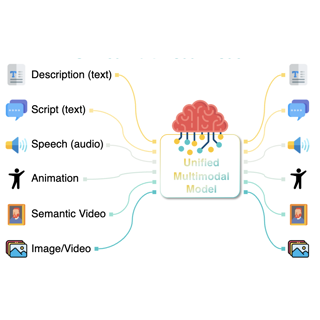
Chong Bao*, Shichen Liu*, Lijun Yu, David Futschik, Stylianos Moschoglou, Shefali Srivastava, Ziqian Bai, Feitong Tan, Guofeng Zhang, Zhaopeng Cui, Sean Fanello, Yinda Zhang CVPR, 2026 project page / arXiv / code We present a unified multimodal model for holistic digital human generation and understanding across text, audio, motion, semantic video, image, and video. |
|
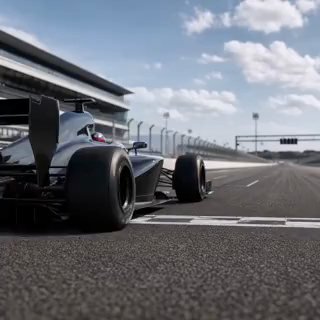
Shuailei Ma*, Jiaqi Liao*, Xinyang Wang*, Jingjing Wang*, Chaoran Feng, Zijing Hu, Chong Bao, Zichen Xi, Yuqi Gan, Weisen Wang, Yanhong Zeng, Qin Zhao, Zifan Shi, Wei Wu, Hao Ouyang, Qiuyu Wang, Shangzhan Zhang, Jiahao Shao, Yipengjing Sun, Liangxiao Hu, Lunke Pan, Nan Xue, Kecheng Zheng, Yinghao Xu, Xing Zhu, Yujun Shen, Ka Leong Cheng Technical Report, 2026 project page / arXiv / code We scale a DiT-based mixture-of-experts video foundation model with more than 70,000 hours of embodied data for physically grounded video generation and embodied intelligence. |
|
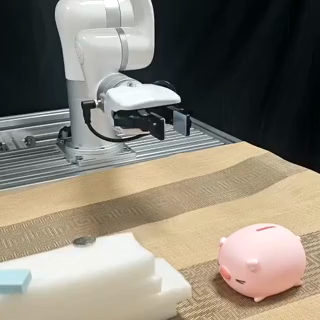
Jingjing Wang, Zhengdong Hong, Chong Bao, Yuke Zhu, Junhan Sun, Guofeng Zhang Preprint, 2026 project page We lift image-editing outputs into continuous, geometry-aware 3D transformations that serve as general priors for open-world robotic manipulation. |
|
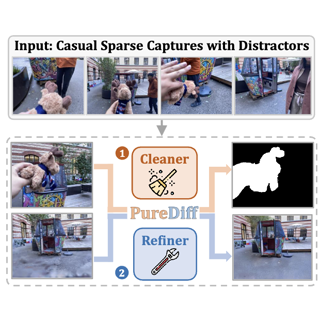
Qirui Hu, Jingjing Wang, Chong Bao†, Xiyu Zhang, Hujun Bao, Zhaopeng Cui, Guofeng Zhang† IJCNN, 2026 We introduce a one-step diffusion model that purifies sparse-view reconstructions corrupted by distractors, improving multi-view consistency and rendering quality. |
|
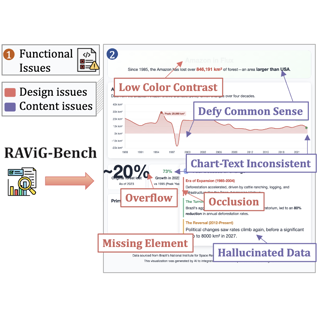
Qirui Hu, Shunlei Ning†, Chong Bao†, Guanyu Chen, Jiaotuan Wang, Wei Yang, Hao Chen, Xuepeng Jia, Wei Zhou, Guofeng Zhang† KDD, 2026 paper / code We introduce a benchmark and multimodal automated evaluation framework for retrieval-augmented visually-rich generation, covering execution correctness, design quality, and content quality. |
|
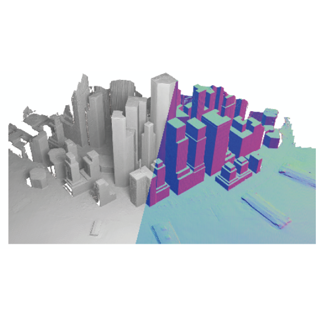
Xiyu Zhang*, Chong Bao*, Yipeng Chen, Hongjia Zhai, Yitong Dong, Hujun Bao, Zhaopeng Cui, Guofeng Zhang NeurIPS, 2025 project page / arXiv / code We propose an Atlanta-world guided, implicit-structured Gaussian representation for efficient and smooth surface reconstruction in indoor and urban scenes. |
|
Jingjing Wang*, Qirui Hu*, Chong Bao†, Yuke Zhu, Hujun Bao, Zhaopeng Cui, Guofeng Zhang† ICCV, 2025 project page / paper / code We present a large-scale synthetic urban dataset with diverse, controllable illumination for benchmarking intrinsic decomposition, inverse rendering, and multi-illumination reconstruction. |
|
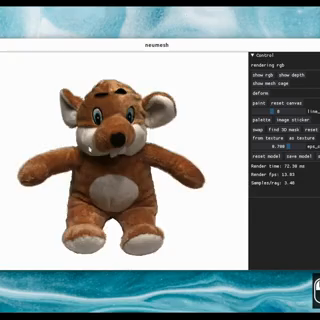
Chong Bao*, Yuan Li*, Bangbang Yang, Yujun Shen, Hujun Bao, Yinda Zhang, Zhaopeng Cui, Guofeng Zhang TPAMI, 2025 project page / arXiv / code We extend neural mesh-based implicit fields with geometry, texture, and semantic controls for versatile, efficient, and interactive volumetric editing. |
|
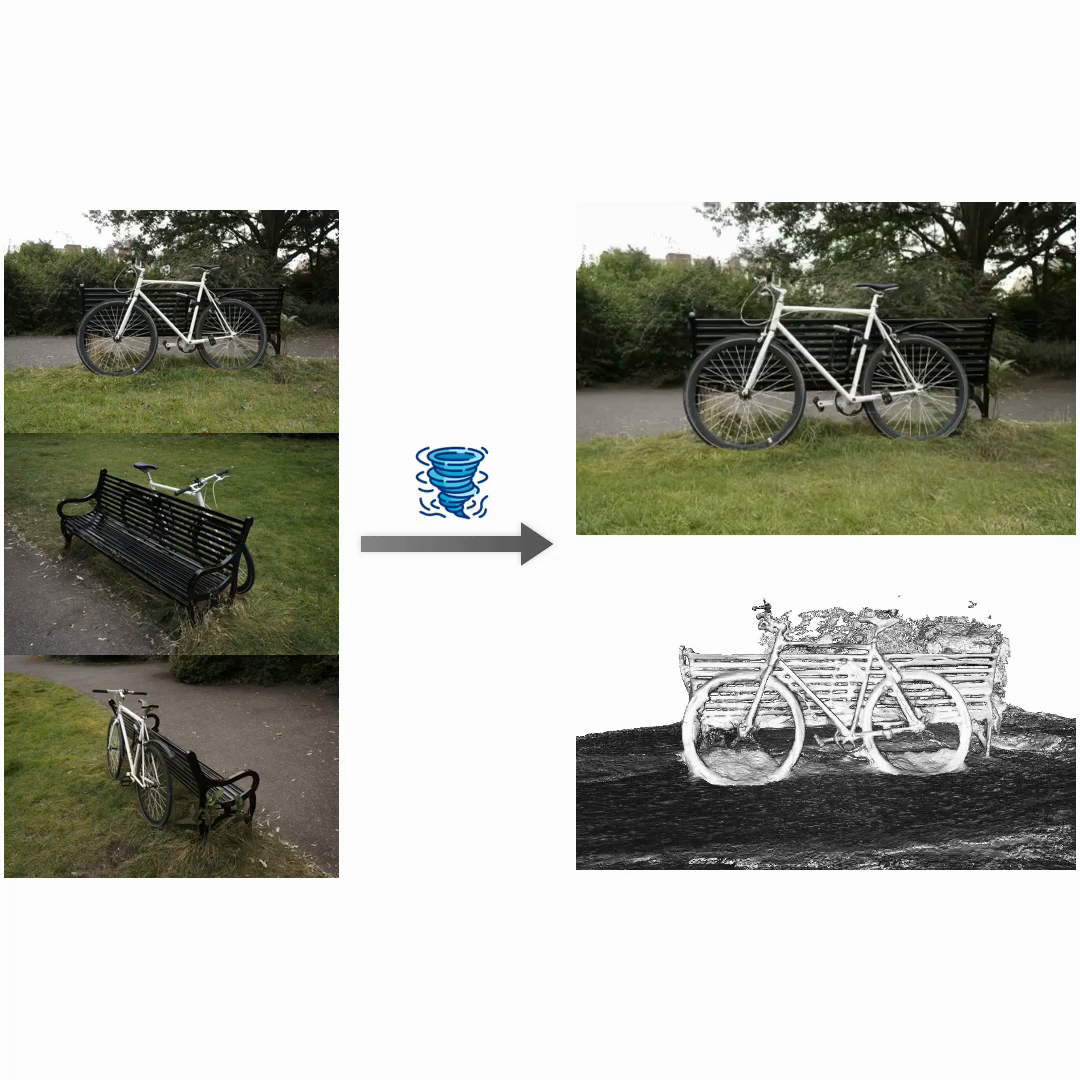
Chong Bao, Xiyu Zhang, Zehao Yu, Jiale Shi, Guofeng Zhang, Songyou Peng, Zhaopeng Cui CVPR, 2025 project page / arXiv / video / code We propose a new GS with video diffusion model for novel view synthesis and surface reconstruction from extremely sparse(3-4), unposed images in unbounded 360 scenes. |
|
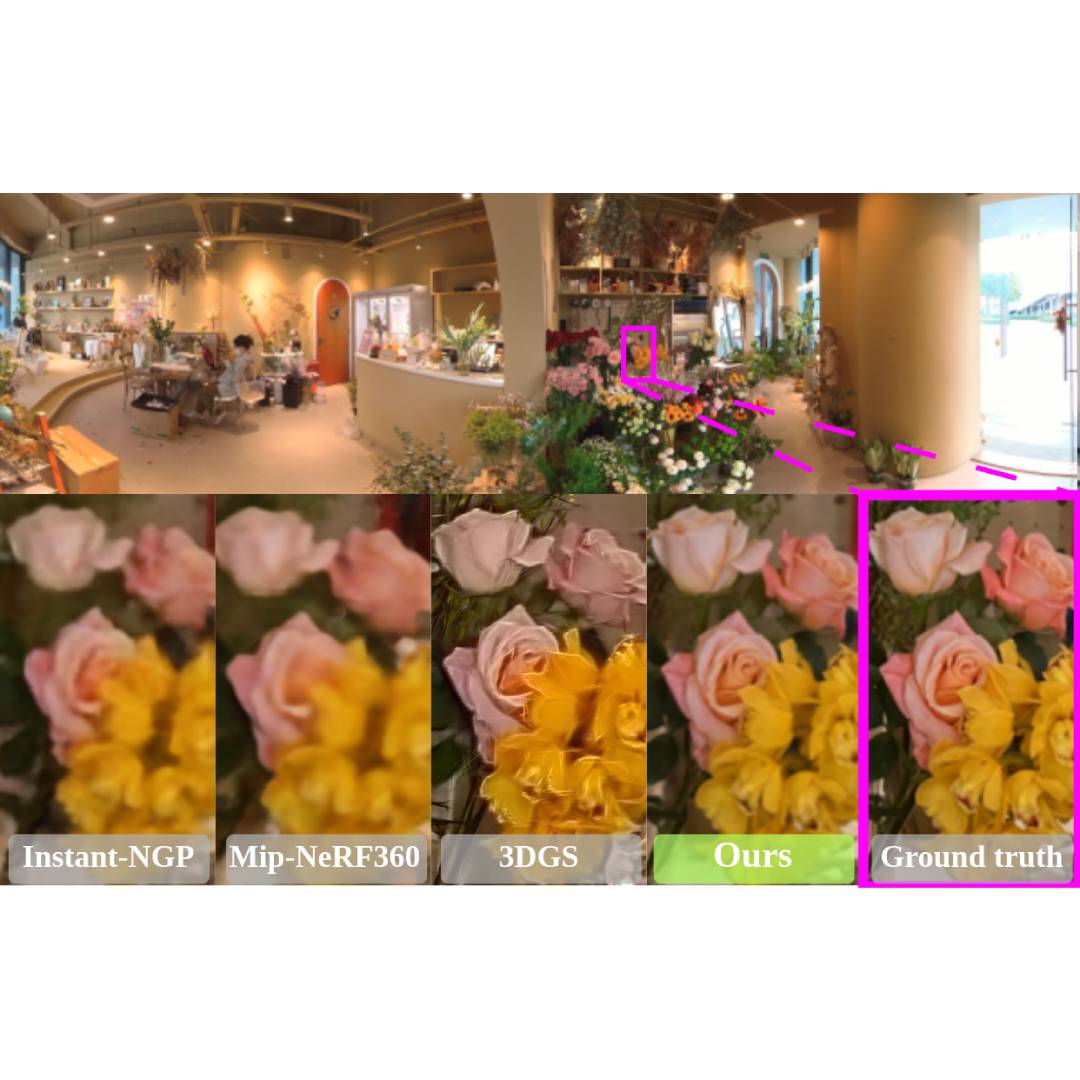
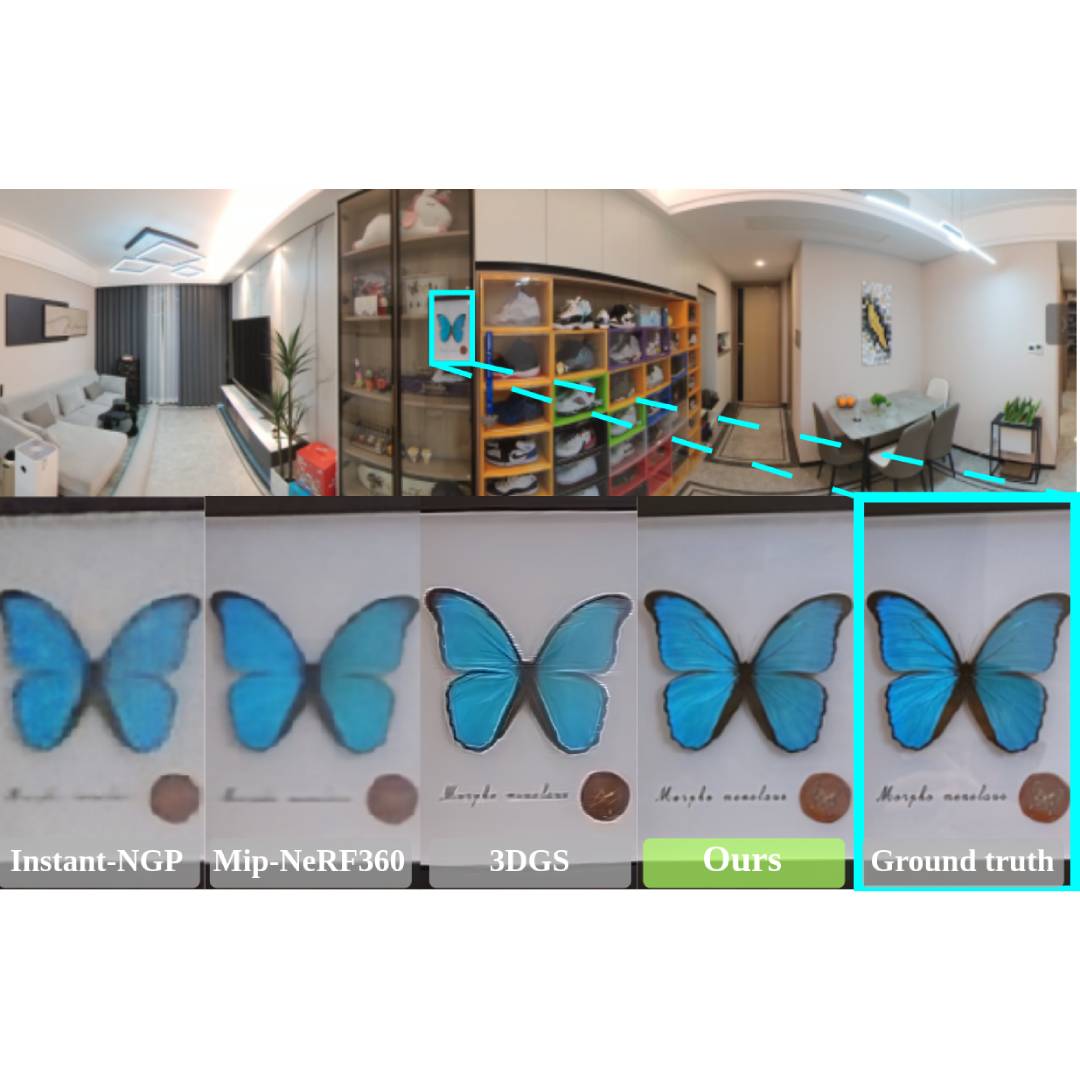
Xiaoyu Zhang, Weihong Pan, Chong Bao, Xiyu Zhang, Xiaojun Xiang, Hanqing Jiang, Hujun Bao, CVPR, 2025 project page / arXiv / code We introduce a novel frequency-aware framework for view synthesis that simultaneously captures the overall scene structure and high-definition details within a single NeRF model. |
|
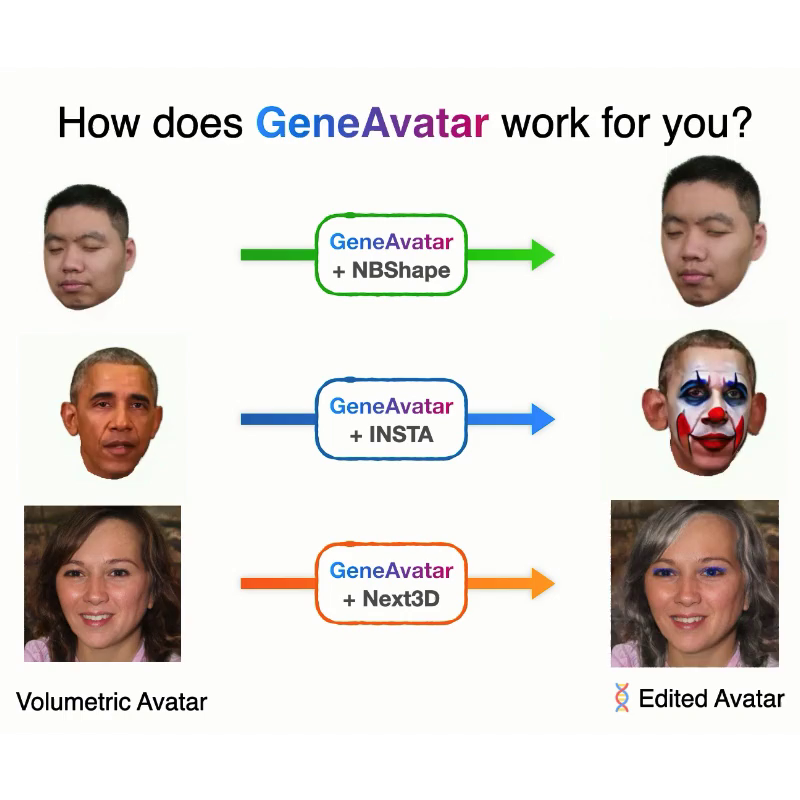
Chong Bao*, Yinda Zhang*, Yuan Li*, Xiyu Zhang, Bangbang Yang, Hujun Bao, Marc Pollefeys, Guofeng Zhang, Zhaopeng Cui CVPR, 2024 project page / arXiv / video / code We present a generic approach to edit 3D avatars in various volumetric representations from a single perspective. |
|
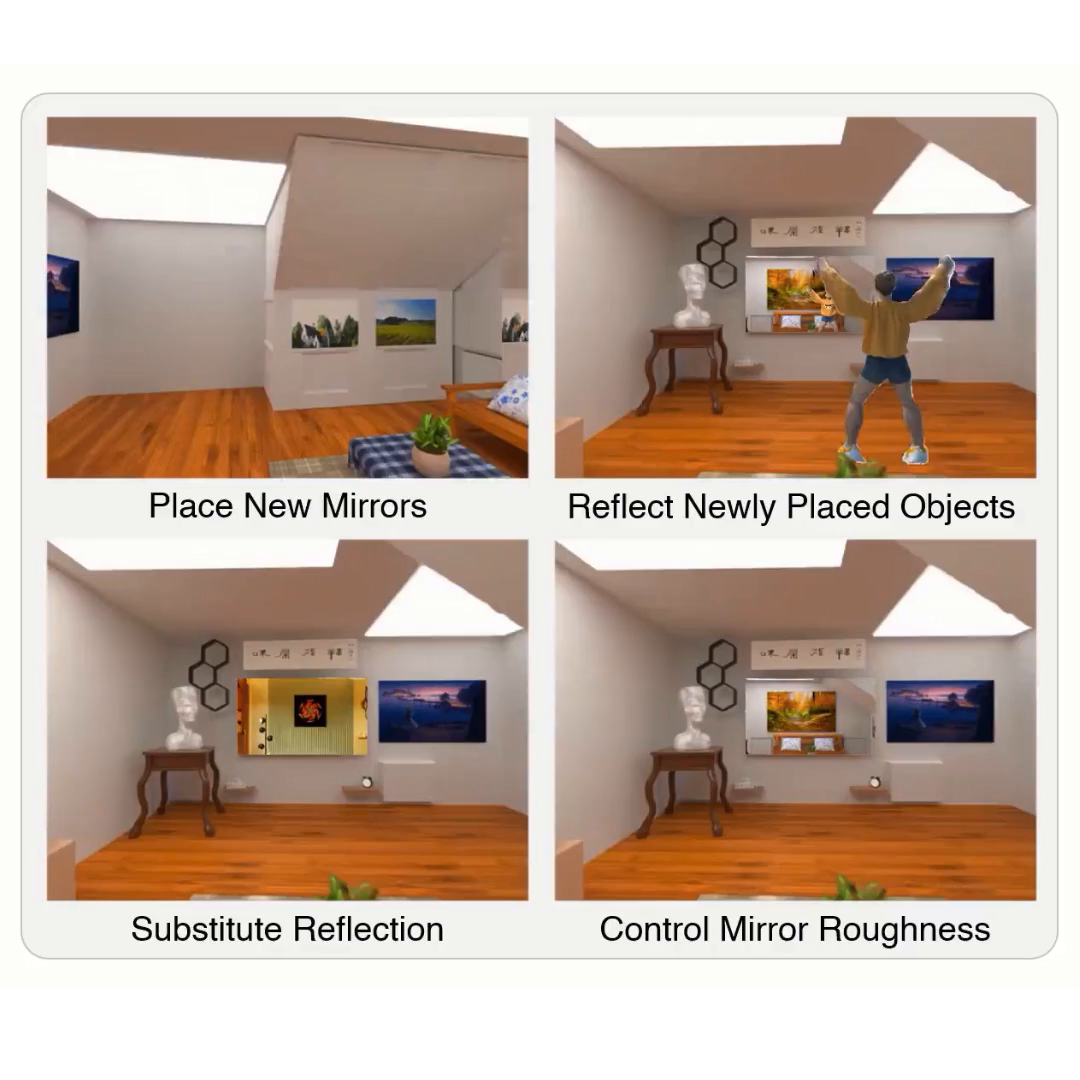
Junyi Zeng*, Chong Bao*, Rui Chen, Zilong Dong, Guofeng Zhang, Hujun Bao, Zhaopeng Cui MM, 2023 project page / arXiv / video / code We present a novel neural rendering framework, which is able to learn accurate geometry and reflection of the mirror and support various scene manipulation applications. |
|
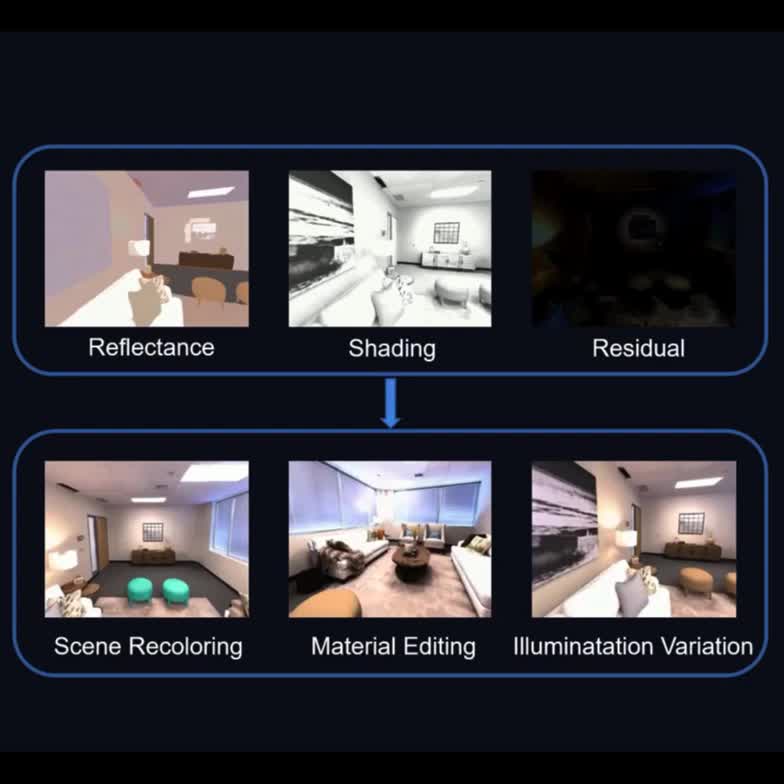
Weicai Ye*, Shuo Chen*, Chong Bao, Hujun Bao, Marc Pollefeys, Zhaopeng Cui, Guofeng Zhang ICCV, 2023 project page / arXiv / code We introduce intrinsic decomposition into the NeRF-based neural rendering method and can perform editable novel view synthesis in room-scale scenes. |
|
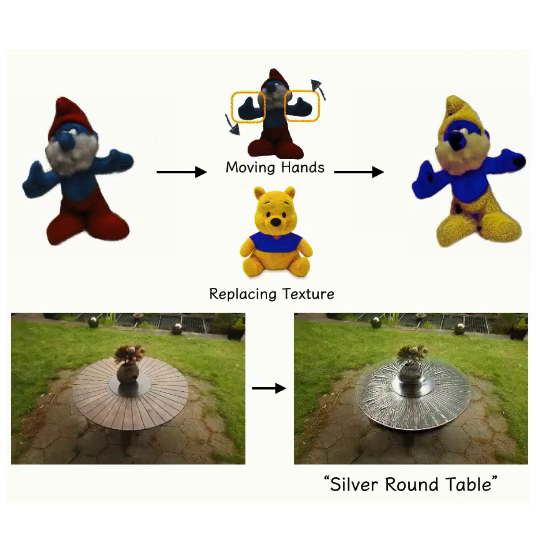
Chong Bao*, Yinda Zhang*, Bangbang Yang*, Tianxing Fan, Zesong Yang, Hujun Bao, Guofeng Zhang, Zhaopeng Cui CVPR, 2023 project page / arXiv / video / code We present a novel semantic-driven NeRF editing approach, which enables users to edit a neural radiance field with a single image. |
|
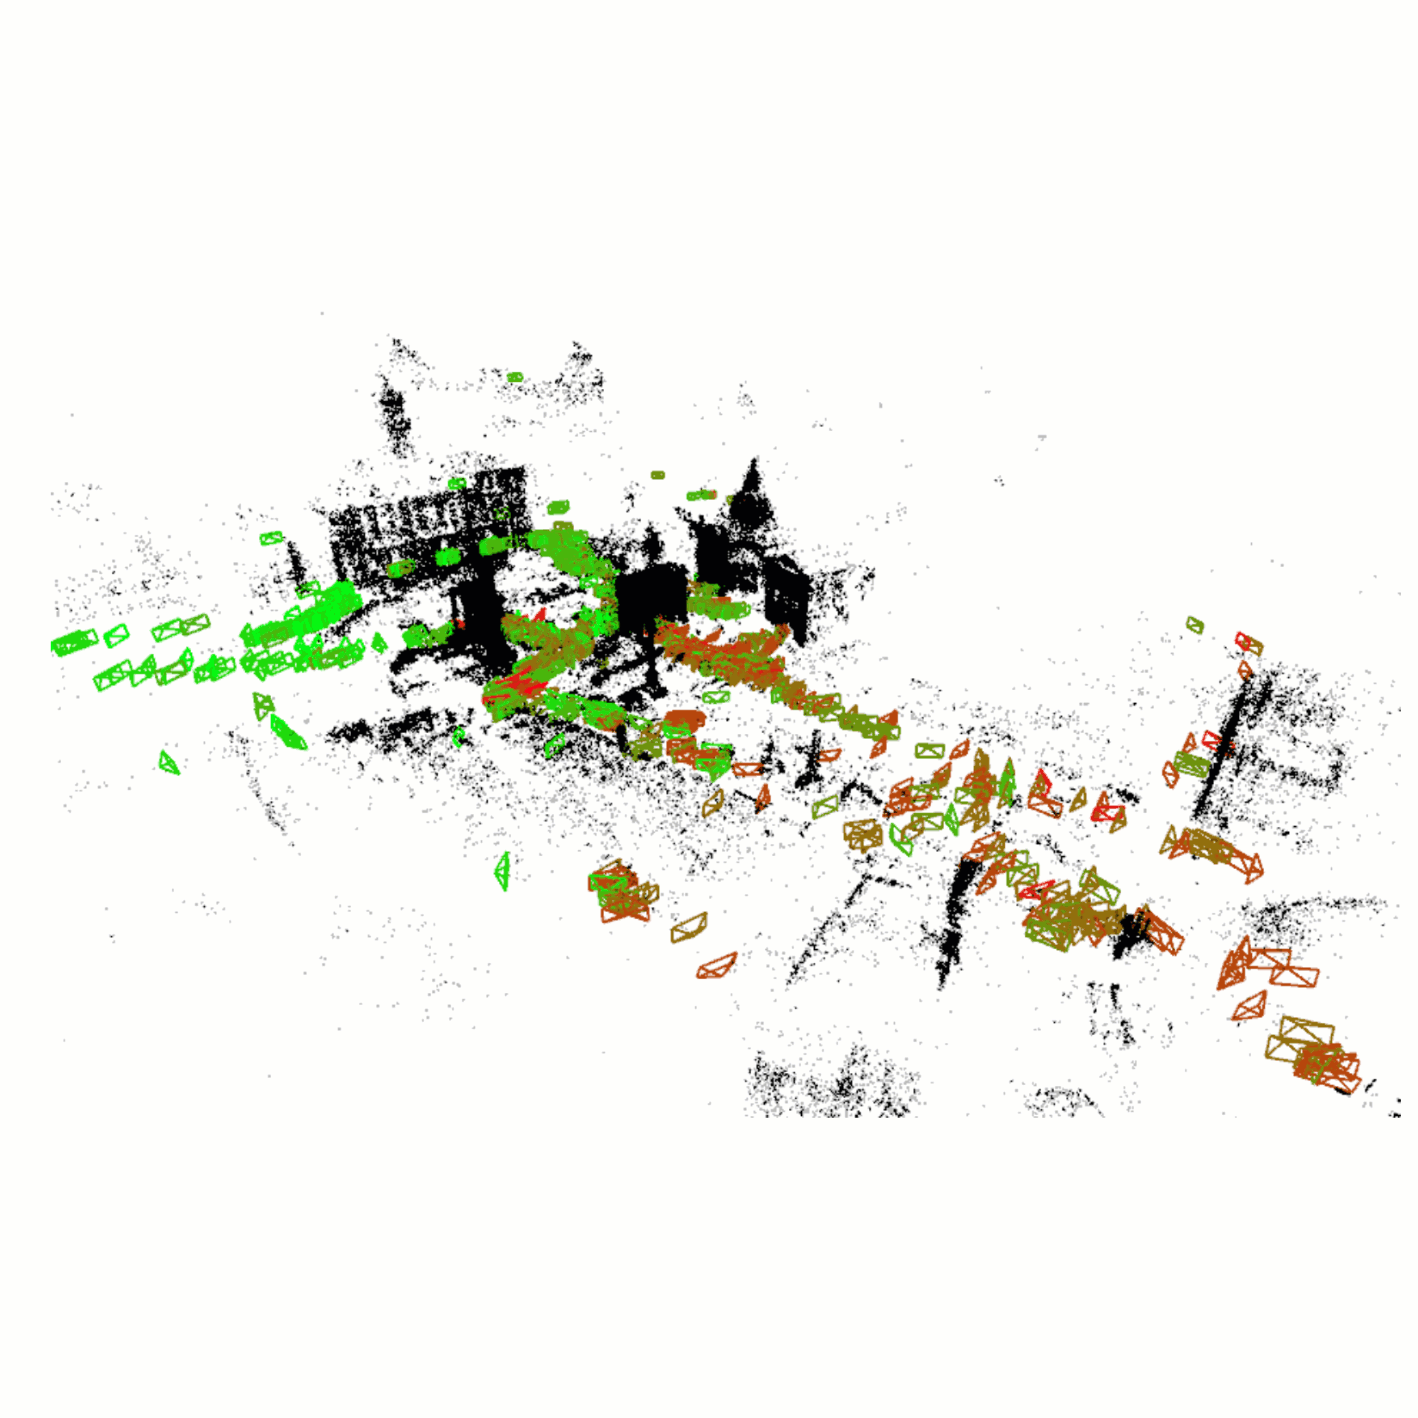
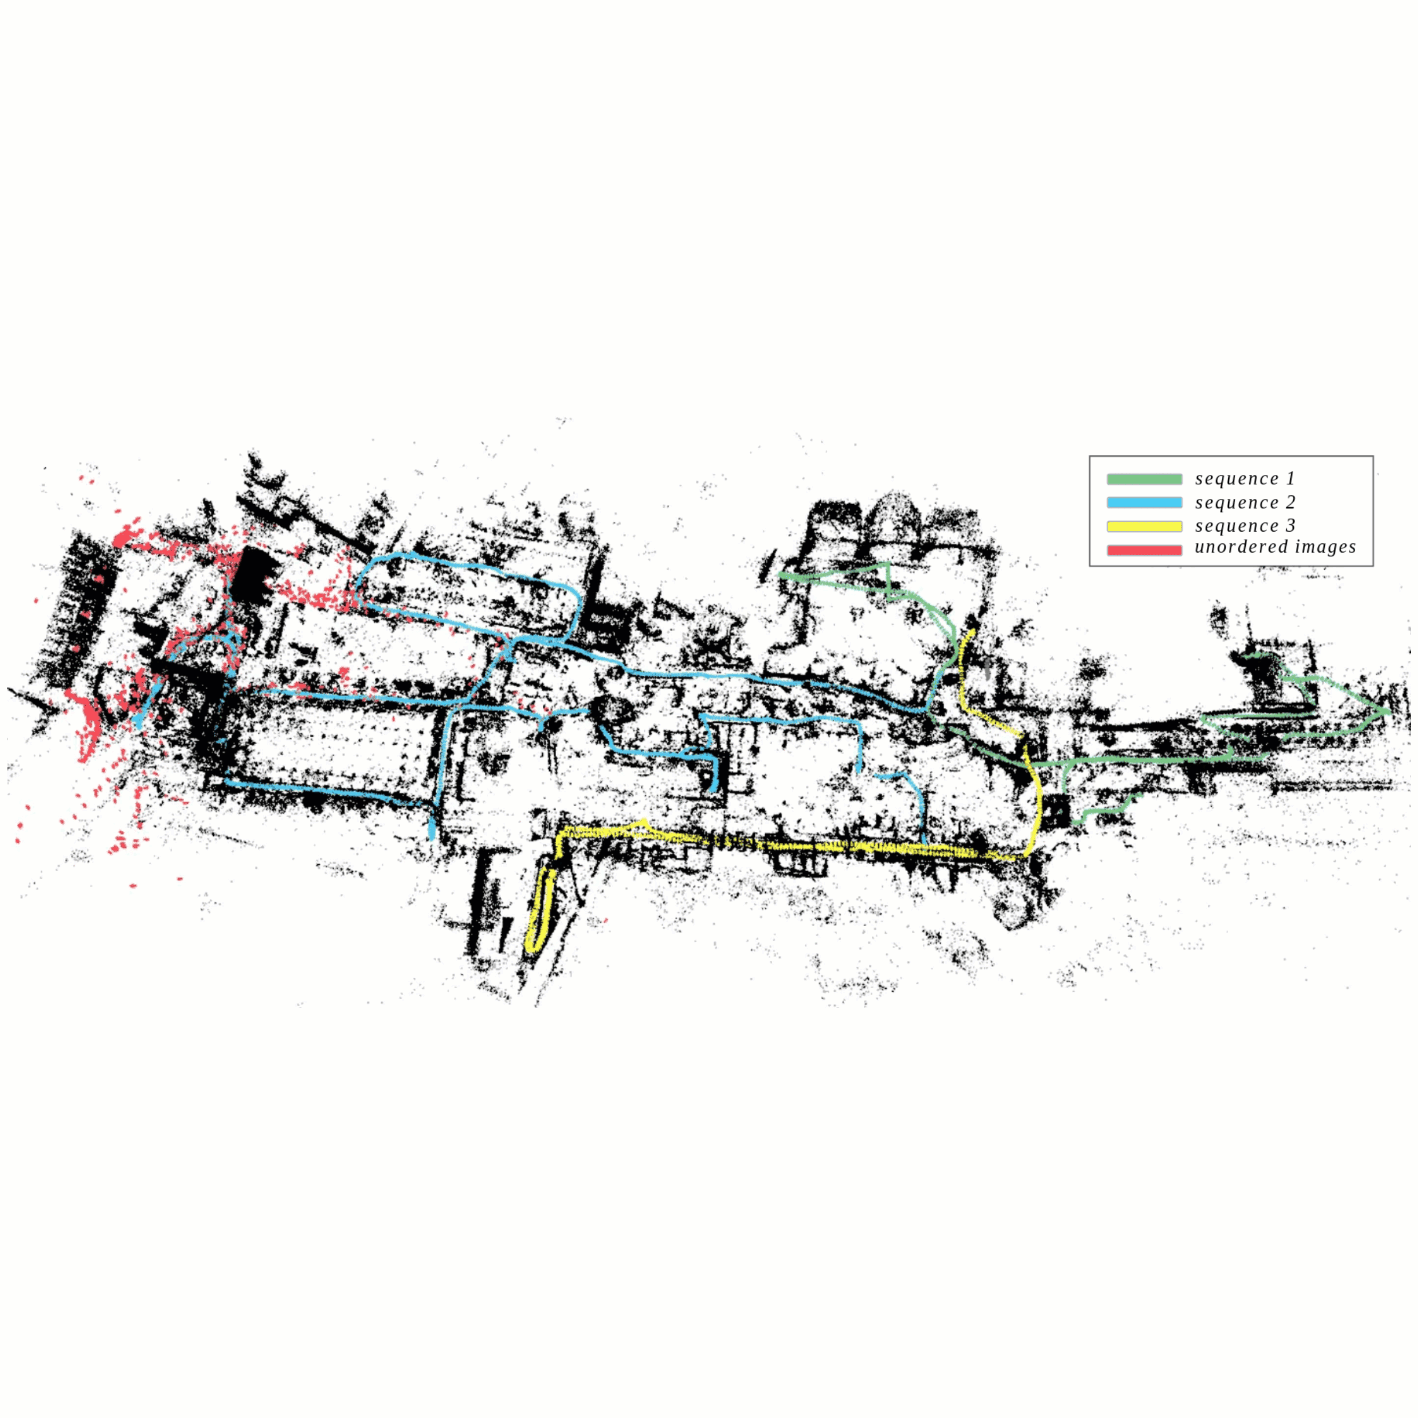
Zhichao Ye, Chong Bao, Xin Zhou, Haomin Liu, Hujun Bao, Guofeng Zhang TCSVT, 2023 paper / arXiv / code We present an efficient covisibility-based incremental SfM and exploit covisibility and registration dependency to describe the image connection |
|
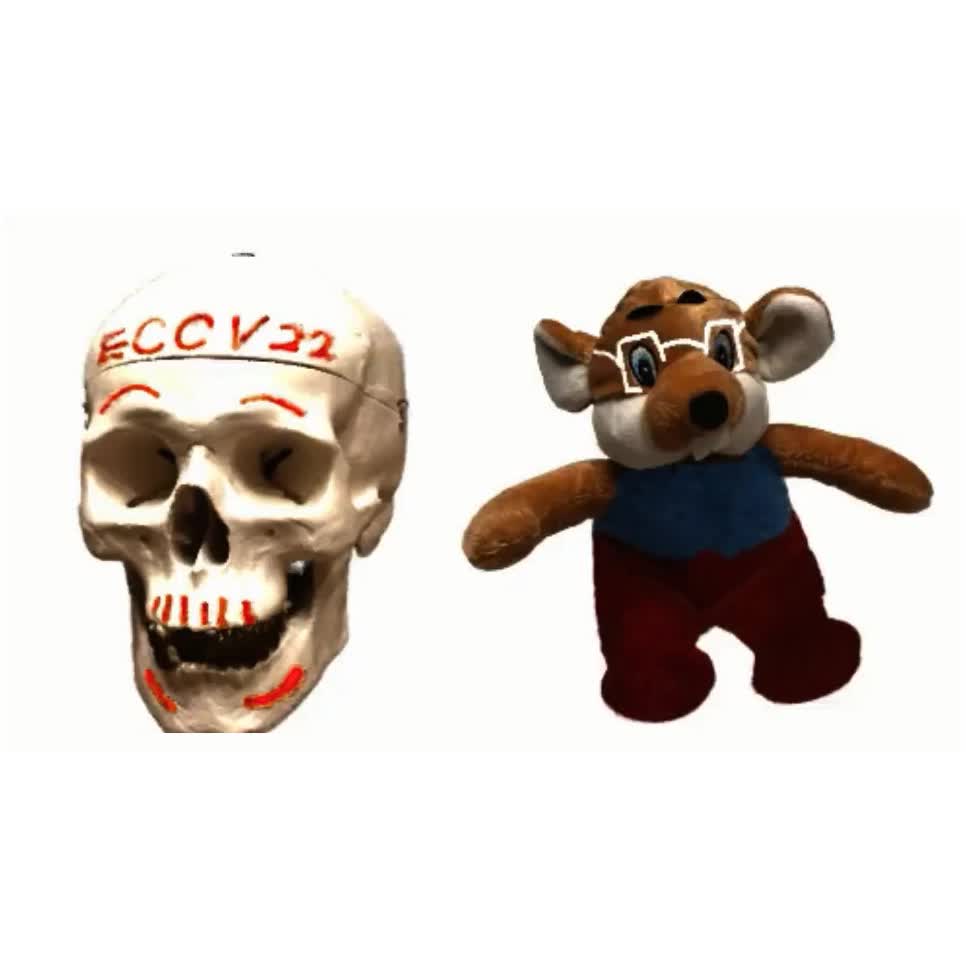
Bangbang Yang*, Chong Bao*, Junyi Zeng, Hujun Bao, Yinda Zhang, Zhaopeng Cui, Guofeng Zhang ECCV, 2022 (Oral Presentation) project page / arXiv / video / code We present a novel mesh-based implicit field with disentangled geometry and texture codes on mesh vertices, which facilitates a set of editing functionalities. |
|
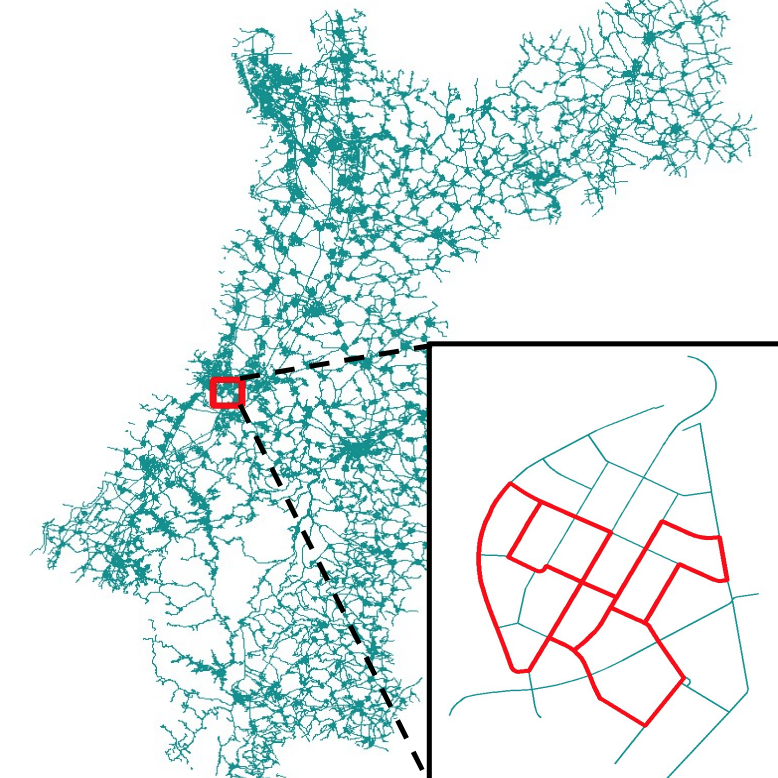
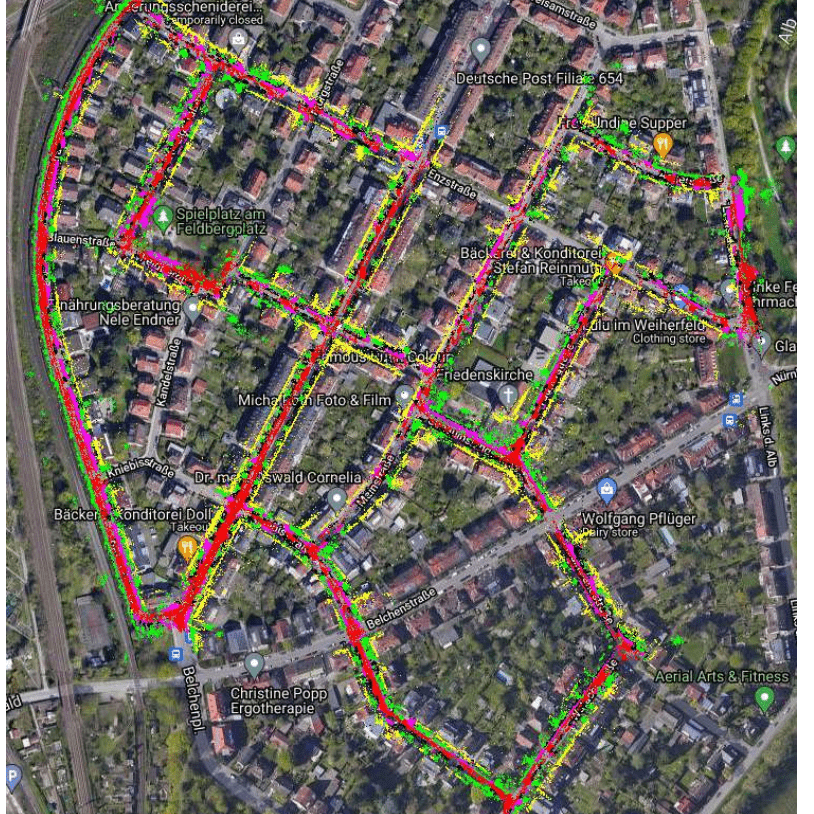
Zhichao Ye, Chong Bao, Xinyang Liu, Hujun Bao, Zhaopeng Cui, Guofeng Zhang ICRA, 2022 paper We present a low-cost mapping solution that is able to refine and align the monocular reconstructed point cloud given a public street map. |
|
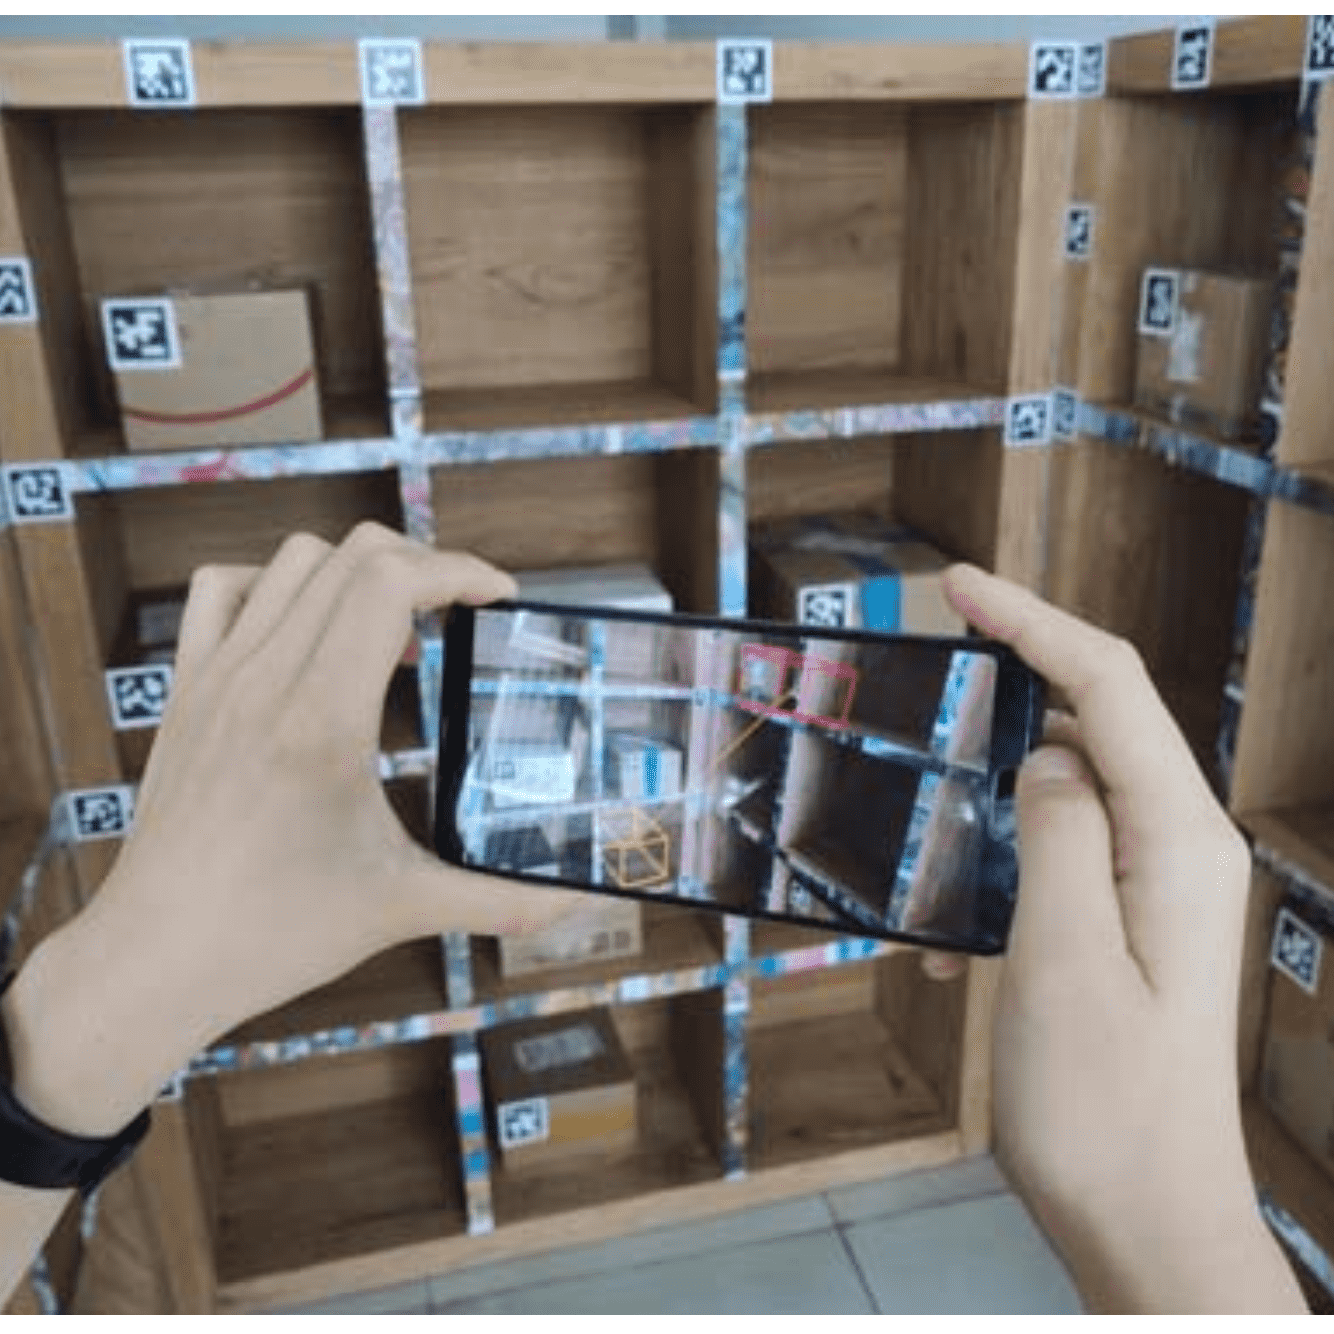
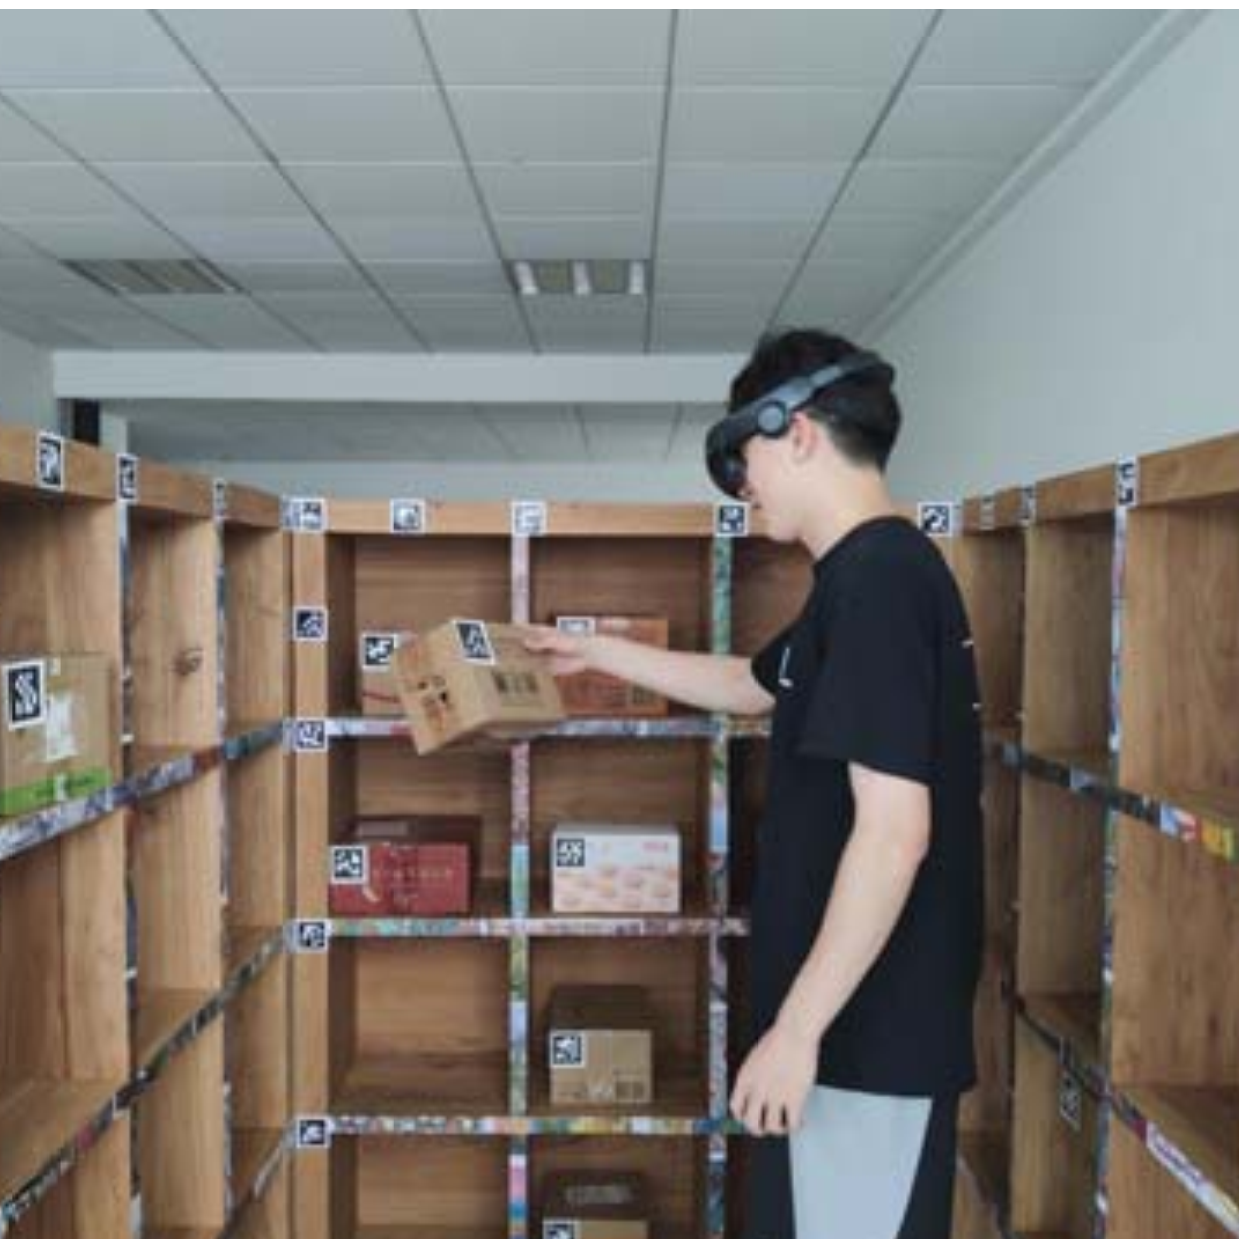
Tianxiang Zhang*, Chong Bao*, Hongjia Zhai*, Jiazhen Xia, Weicai Ye, Guofeng Zhang CyberSciTech, 2021 paper / video We present a multi-device integrated cargo loading management system with AR, which monitors cargoes by fusing perceptual information from multiple devices in real-time. |
|
|
 |
Research Intern
Inspatio 2026.08-2026.09 |
 |
Research Intern
Ant Group, Robbyant/Lingbot 2026.02-2026.08 |
 |
Student Researcher
Google XR 2025.03-2025.11 |
 |
Visiting Student
Computer Vision and Geometry Lab, ETH Zürich supervised by Marc Pollefeys 2023.09-2024.09 |
 |
Research Intern
Multi-sensor Fusion Localization Group, Sensetime 2020.07-2020.09 |
 |
Research Intern(Star of Tomorrow)
Internet Graphics Group, Microsoft Research Asia(MSRA) 2020.04-2020.07 |
|
|
|
Ziyang Zhang, Chong Bao, Hai Li, First prize in China Mobile Application Innovation Competition, held by Apple. , 2021 appstore We develop a platform realizing augmented urban reality based on scene localization. |
|
Design and source code from Jon Barron's website |